Abstract
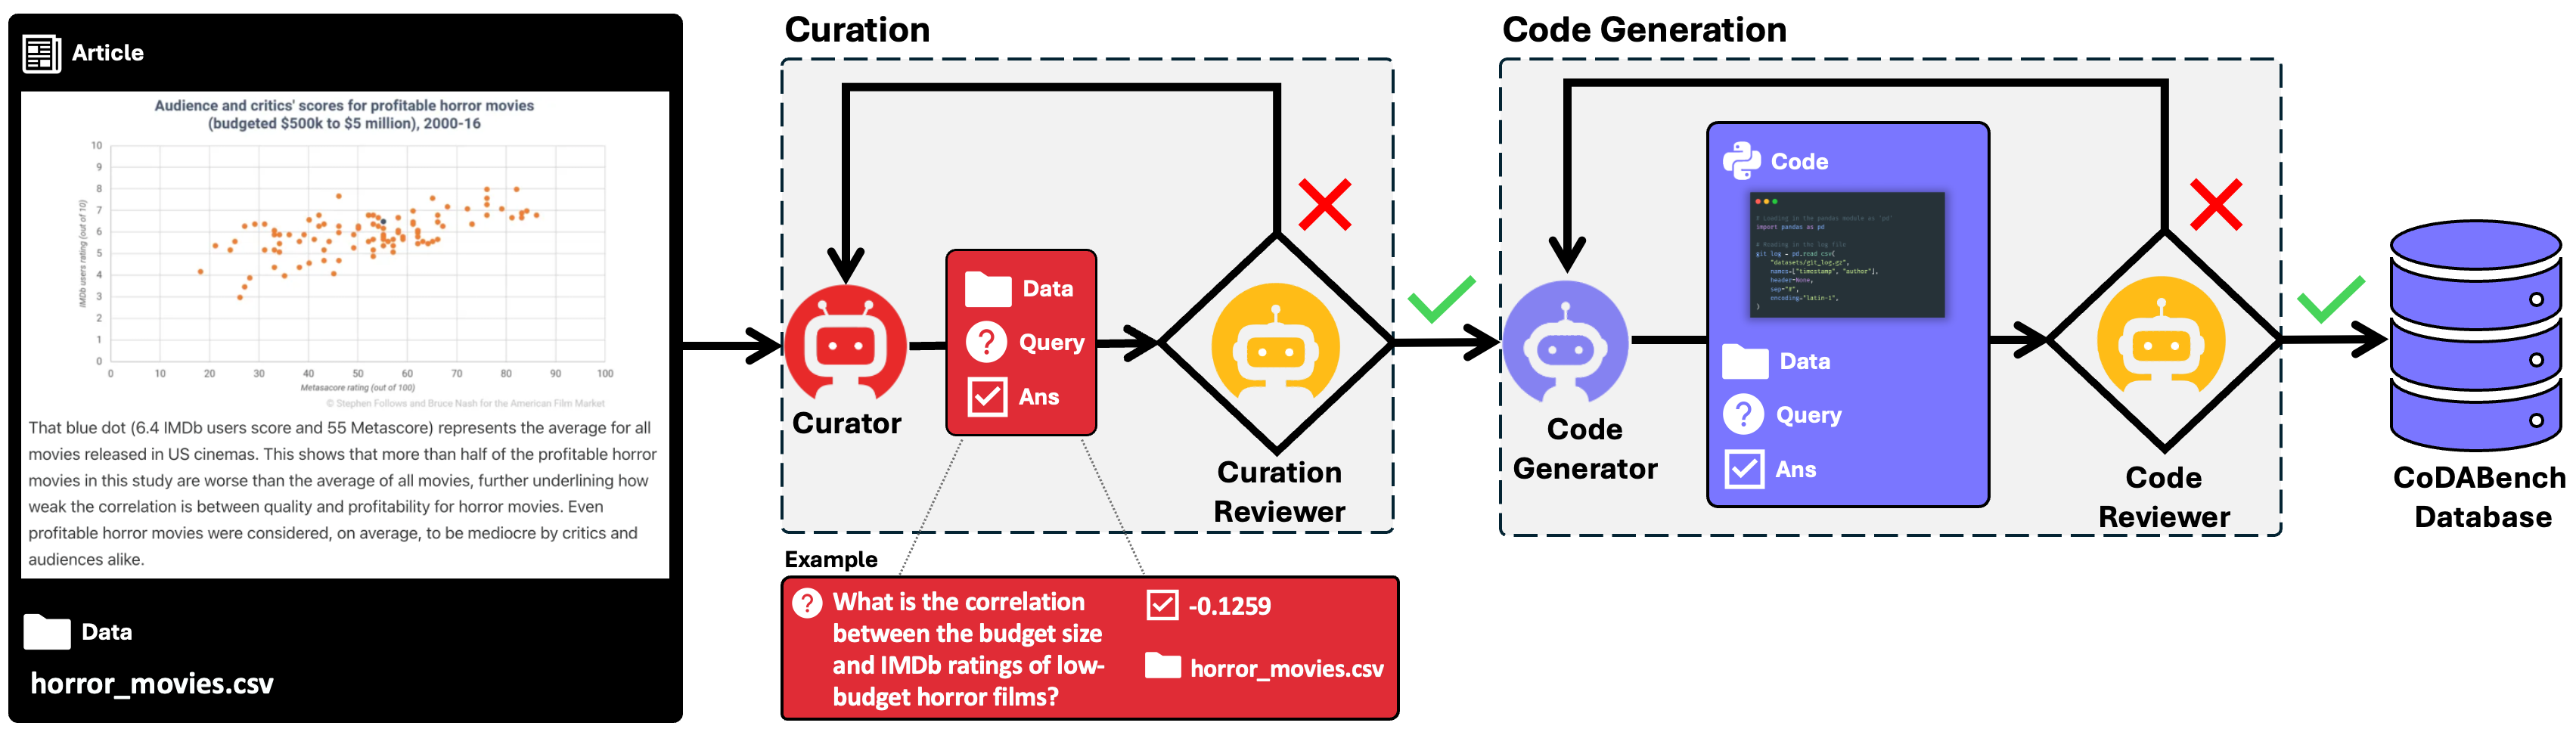
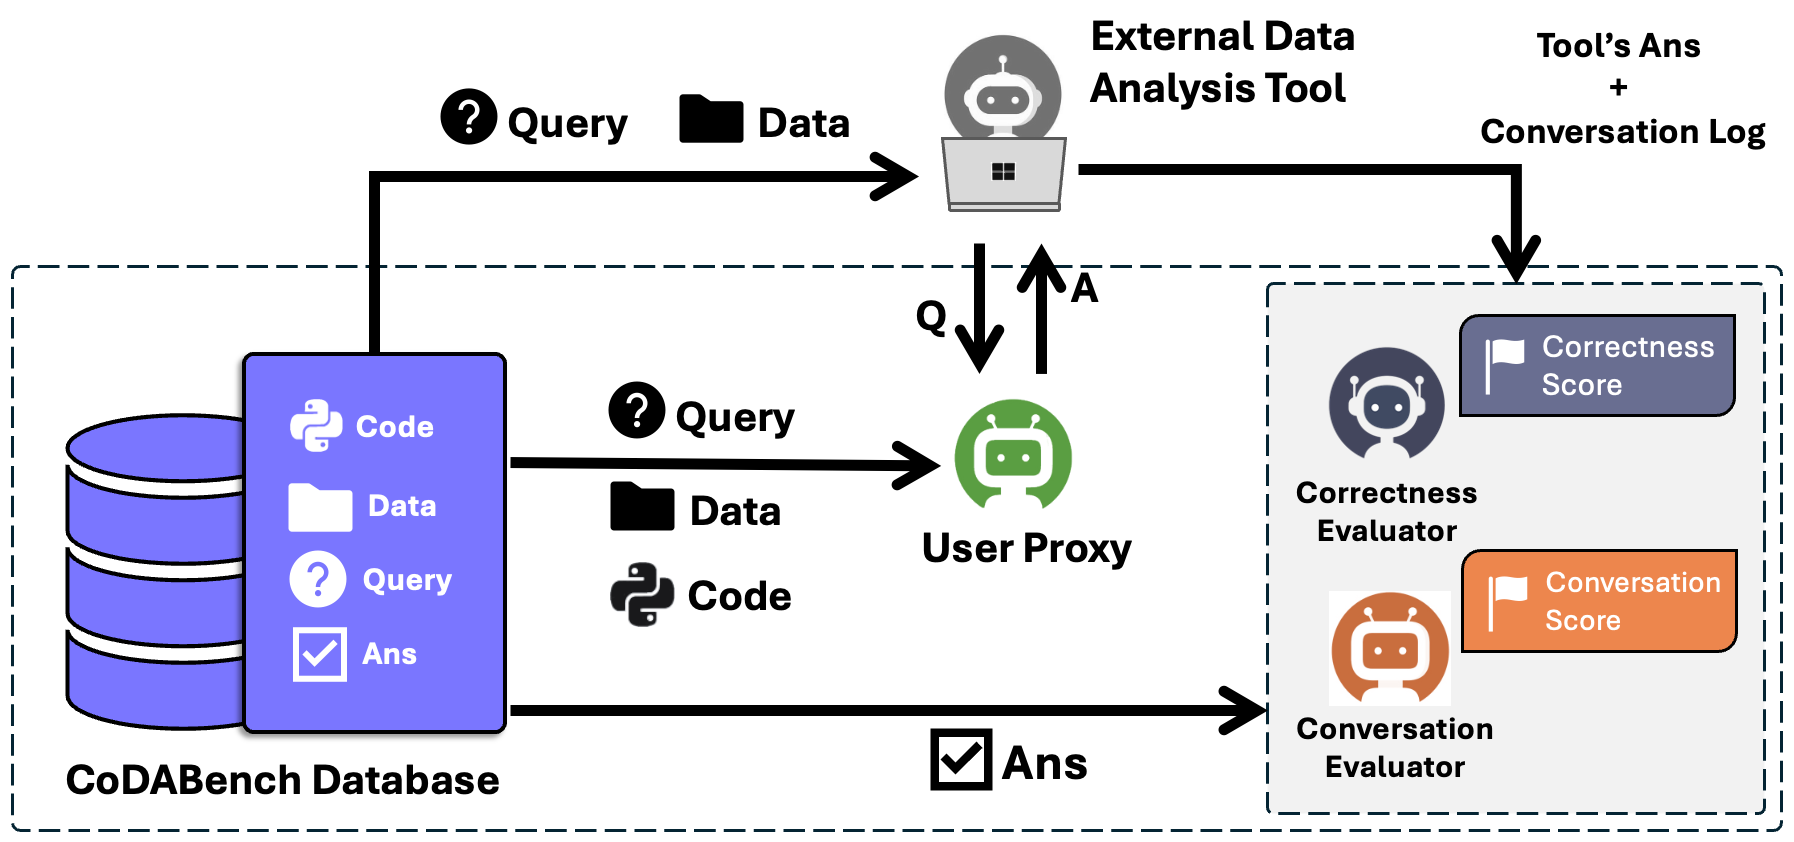
Real-world data analysis tasks often come with under-specified goals and unclean data. User interaction is necessary to understand and disambiguate a user's intent, and hence, essential to solving these complex tasks. Existing benchmarks for evaluating LLMs on data analysis tasks do not capture these complexities or provide first-class support for interactivity. We introduce ConDABench, a framework for generating conversational data analysis (ConDA) benchmarks and evaluating external tools on the generated benchmarks. ConDABench consists of (a) a multi-agent workflow for generating realistic benchmarks from articles describing insights gained from public datasets, (b) 1,420 ConDA problems generated using this workflow, and (c) an evaluation harness that, for the first time, makes it possible to systematically evaluate conversational data analysis tools on the generated ConDA problems. Evaluation of state-of-the-art LLMs on the benchmarks reveals that while the new generation of models are better at solving more instances, they are not necessarily better at solving tasks that require long conversations. ConDABench is an avenue for model builders to measure progress towards truly collaborative models that can complete complex interactive tasks.
 ConDABench
 Microsoft